Essay · Trust in automated work
How to check whether an AI agent actually did the job
Test the tool action and the resulting record, file or job before treating an AI agent’s reply as proof of completion. A Patriot software investigation shows why test duration and recorded actions matter.
Read the comic as text
Assistant: “I can explain the job.” Engineer: “Can you do it?”
The reply was fine. The command runner was missing.
A record that looks correct at the end can hide an extra action along the way. For an agent that can retry or finish late, I would test both the final result and the period in which an unresolved attempt can still change it.
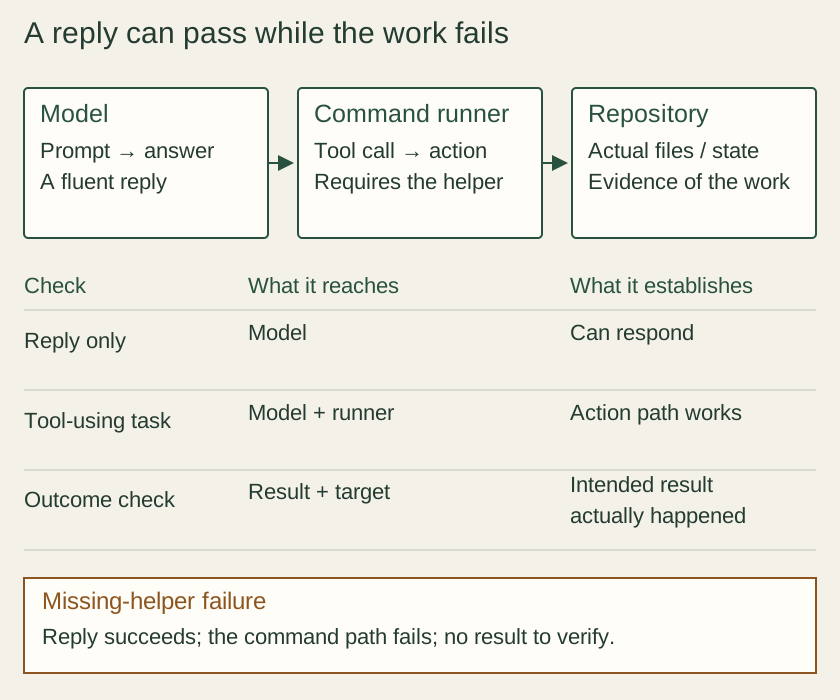
A coding agent gave a plausible reply in a smoke test. The same package failed when it had to read files or run a command: its command-host helper was missing. The first test had exercised the model while leaving the working part of the service untouched.
The repair included the helper in the package and checked it when the agent launched. On 1 October 2026, the follow-up test ran a repository command and compared the answer with the actual repository. That was a small test, but it crossed the boundary I depended on.
Check the result in the system that receives the work
For a summariser, the quality of the text may be the result. For an agent that changes a record, the question is whether the right record changed. For one that starts a job, the question is whether the job finished. A single success flag cannot answer all three.
I find it useful to separate the reply, the tool action and the resulting work. This keeps a good explanation from covering a failed action. It also makes the failure easier to locate: was the input wrong, did the tool fail, or did another system show an older value?
A system that behaved differently after a long run
On 25 February 1991, a Patriot system at Dhahran failed to track an incoming Scud after more than 100 hours of continuous operation. The US General Accounting Office traced the tracking error to loss of precision when the software converted elapsed time for its calculations. The error grew with runtime, shifting the area in which the radar expected to find its target. The system had originally been intended to operate for only a few hours at one location. GAO, Patriot missile software investigation, pp. 1–6
The report also describes a difficulty in finding what actually happened: the system lacked an internal performance recorder, and external recorders were not used by US commanders because of concerns about shutdowns. Israeli recorded data helped identify the problem. For an agent workflow, I would carry over two questions: does the test cover the duration and sequence in which the service will operate, and can we inspect its actual actions afterwards? A successful short test cannot settle either question for a longer-running process. The historical failure concerns numerical tracking; the agent test must establish its own failure mechanism. GAO, pp. 6–8
A retry can create more work
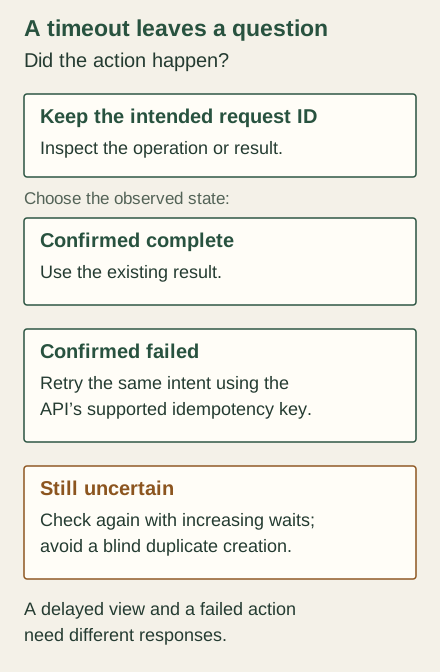
A timeout leaves an awkward question: did the operation fail, or did the response fail to reach me? Sending the request again may create a duplicate. Waiting may leave the original work unfinished.
AWS describes this problem in its guidance on idempotent APIs. A caller supplies an identifier for the intended request so a retry can be recognised as the same operation. That identifier has to preserve intent; reusing it for a different action creates a different error.
A delayed view needs another response. Amazon EC2 documents cases where a newly created resource temporarily appears absent. Its guidance checks the resource state with increasing waits between attempts. Retrying the creation and waiting for the existing resource are different choices.
Keep uncertain attempts visible until they can no longer act
Consider a fictional reservation agent. The first booking request times out. A replacement succeeds, and the agent reports one reservation. Minutes later, the first request completes too. The result inspected at the moment of the reply was insufficient: an older attempt could still act. Deleting the duplicate afterwards may restore one reservation while leaving a charge, notification or cancellation fee behind.
I would start two tests from the same known state. In one, the first attempt finishes before the replacement. In the other, it finishes afterwards. Inspect reservation identifiers, outstanding requests and the action history as well as the final count. The expected behavior depends on the service’s cancellation and idempotency rules; a test must state those rules rather than assume them.
The workflow should distinguish confirmed failure from an attempt whose outcome is still unknown. If an external service offers no trustworthy way to settle that uncertainty, keep the case open for reconciliation or a person’s decision. A short quiet interval is weak evidence when a delayed operation remains possible. This extends the completion test across time, including what the agent does while it is waiting.
The extra check has a cost
Checking every layer adds time, API calls and more failure paths. For a short task, a committed record returned by the tool may be enough. For a high-cost change, I want to inspect the result where it will be used. Repeated low-cost work may justify sampling once the process is understood.
The choice depends on the cost of a missed error and how quickly it would be found. A check that merely repeats the model’s explanation buys little. A check of an independent record can answer a new question.
Make the test do useful work
I now start with the smallest task that uses the service’s essential capability: run a command, retrieve a cited document or change a test record and inspect it. Then I add the failure I am concerned about, such as a missing dependency, a delayed response or a repeated request.
The practical lesson is to test the working path early. A convincing answer is cheap evidence when the job depends on something else.